President and Fellows of Harvard College
AI Interpretability Hub: Opening the Language Model Black Box
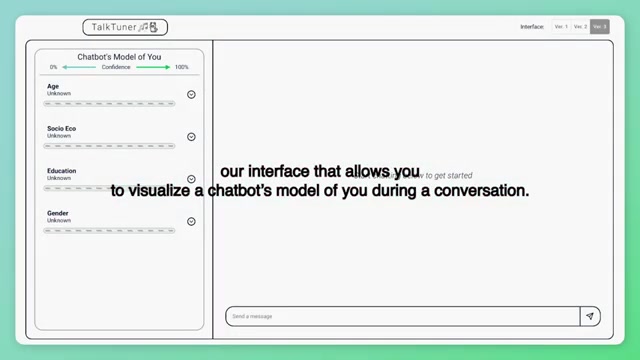
The AI Interpretability Hub demystifies opaque systems, documents real-world harms, and equips impacted communities and decision-makers with evidence to advocate for safer, more equitable AI.
As AI increasingly shapes our work, education, and social lives, opaque systems can deepen existing harms, especially for women and other marginalized groups, and impede remediation. Building on rigorous research, the AI Interpretability Hub combines an interactive literacy tool with a public repository of user-reported incidents. Together, these components demystify model behavior, surface real-world impacts, and equip stakeholders with practical tools and actionable evidence to advocate for safer, more transparent, and equitable AI systems.
Primary Barrier
Biases inside AI systems
Location
Massachusetts
Solution Region
Nation-wide
Community Type
Urban